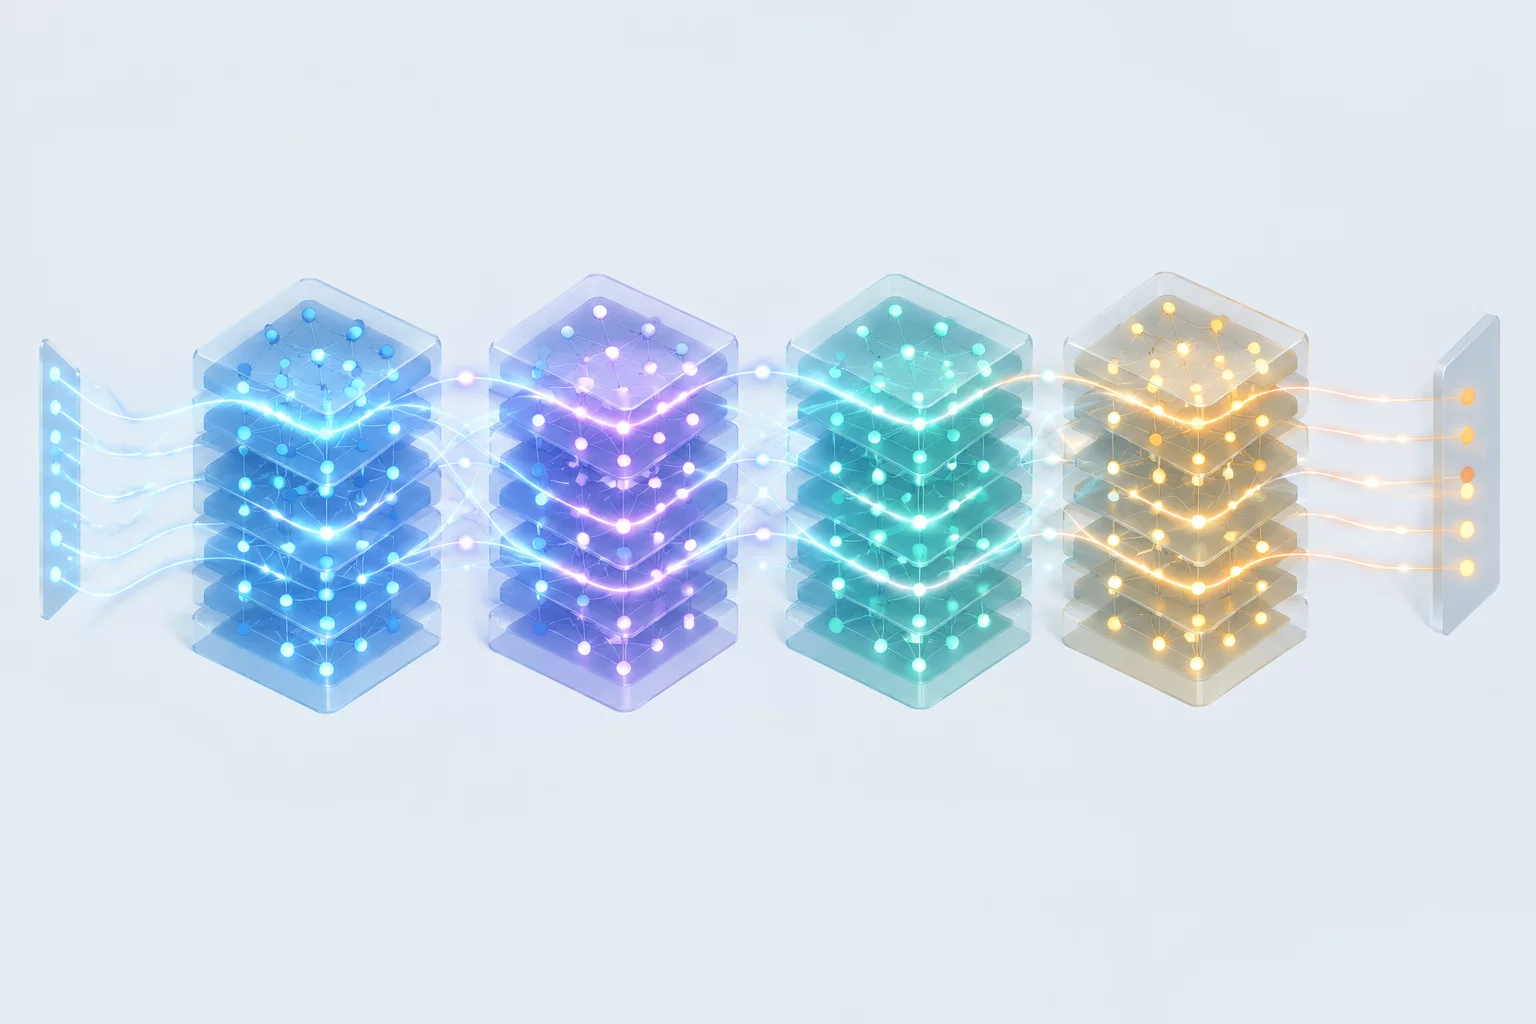
The Shift from Monolithic Systems to Federated Model Routing
Enterprise meeting workflows demand strict latency and high precision that no solitary foundational model delivers effectively. Relying on an isolated generalist engine creates operational bottlenecks, elevates token expenditure, and risks context truncation during dense cross-departmental deliberations. Federated model routing addresses this trade-off by delegating incoming conversational streams to distinct, purpose-tuned models operating in parallel execution threads.
Under this federated model topology, an on-device lightweight engine handles immediate speaker separation and semantic transcription without pushing raw audio off the local computer. Once raw text segments emerge, a middle-tier extraction agent normalizes conversational statements into canonical AGENTS schema formats. Heavy reasoning units receive only distilled operational context when complex consensus evaluation or structured database mutations occur, saving valuable bandwidth and preventing memory leaks.
Deploy Federated Agent Pipelines
Integrate Gramolai to manage multi-model audio ingestion, automatic action routing, and CRM pipeline automation.
Orchestration Topology and Latency Boundaries
Balancing high throughput against deterministic latency requires strict segmentation between transient conversation state and durable enterprise storage. The orchestrator enforces hard execution limits across every specialized agent node, ensuring that background summaries never delay interactive transcription displays.
-
01
Sub-300ms Real-Time Buffering
Audio frames stream through local neural acoustic matrices before any cloud API call, ensuring transcription keeps pace with rapid vocal exchanges.
-
02
Asynchronous Reasoning Queues
Complex corporate entity matching and roadmap conflict evaluations run on worker queues without blocking live transcript views.
-
03
Strict Cryptographic Perimeter Guard
Identifiers, customer financial figures, and employee metrics receive zero-knowledge anonymization hashes before downstream processing begins.
Context Compression and Cross-System Synchronization
Lengthy strategic discussions regularly exceed single-window token limitations unless active context compression operates continuously. Rather than blindly truncating previous minutes, intelligent orchestrators compress resolved discussions into structured state vectors while keeping open decision topics in full fidelity.
- Dynamic semantic summarization removes vocal hesitations and redundant digressions without losing commercial commitments.
- Automated conflict checks verify whether statements made in the current call contradict previous quarterly project commitments.
- Direct AGENTS schema payloads dispatch deterministic parameters directly to Jira, HubSpot, and Salesforce without manual copy-pasting.